

AIOps vs. MLOps vs. DevOps: Where Do They Overlap (and Where They Don’t)?
If you’ve sat in a budget meeting where someone asked “don’t we already have this?” when a new AIOps or MLOps tool came up, you’re not alone. As IT organizations layer AI on top of software delivery on top of infrastructure operations, the lines between DevOps, MLOps, and AIOps blur fast, and that confusion has a real cost: duplicated tooling, unclear ownership when something breaks, and budget requests that are hard to justify because nobody can explain exactly what problem the new platform solves that an existing team doesn’t already own.
This guide breaks down what each discipline actually does, where the three genuinely overlap, where they don’t, and how to decide which one your organization needs first, whether you’re running a lean SaaS platform, a multi-region retail stack, or a regulated fintech or healthcare environment where downtime and model errors carry very different consequences.
The Core Confusion: Why These Three Terms Get Mixed Up
The confusion isn’t really about definitions most engineering teams can recite them. It’s about the fact that all three disciplines rely on automation, all three reduce manual toil, and all three eventually touch the same production environment. That overlap in outcome (faster, more reliable operations) makes it easy to assume overlap in function. They don’t fully overlap, and treating them as interchangeable is where most of the wasted spend happens.
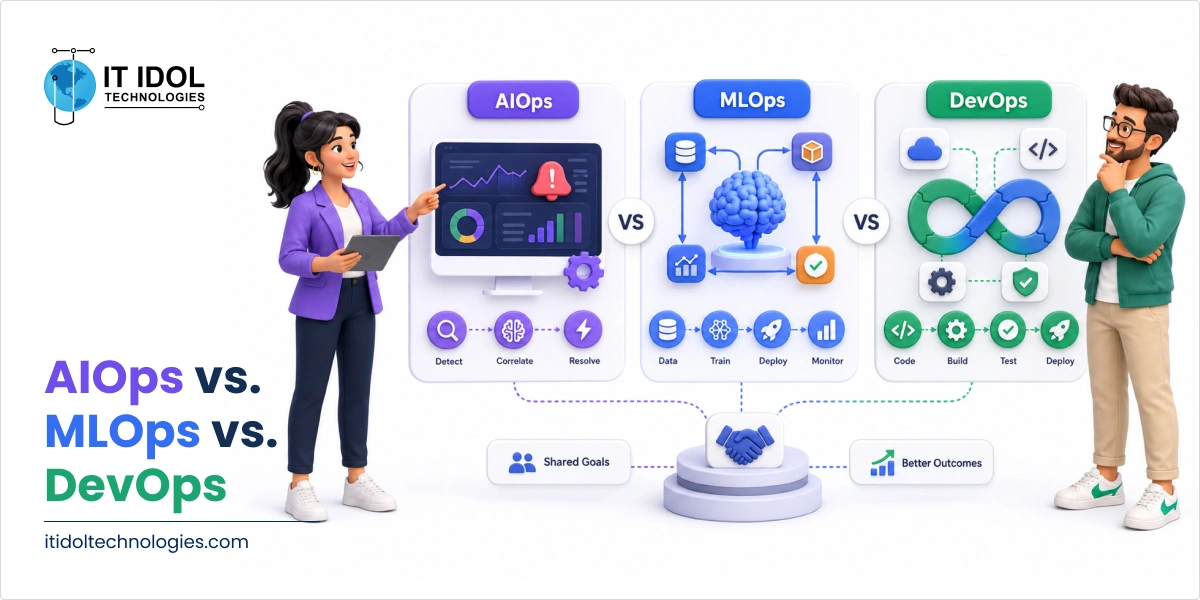
DevOps, in one sentence
DevOps is the discipline of building, testing, and releasing software changes through automated, repeatable pipelines so that deployments stop being risky, manual events.
MLOps, in one sentence
MLOps is the discipline of taking a machine learning model from a data scientist’s notebook into production, then keeping it accurate as real-world data shifts underneath it.
AIOps, in one sentence
AIOps is the use of AI and machine learning to monitor IT operations data logs, metrics, traces, and tickets so that anomalies are detected, correlated, and in many cases resolved before a human ever opens a dashboard.
What Each Discipline Actually Owns
Before looking at where these three meet, it helps to be precise about what each one is accountable for on its own. The table below reflects how these responsibilities typically get divided in a reasonably mature engineering organization; smaller teams often collapse two or three of these into one person’s job, which is fine early on but becomes a bottleneck as systems scale.
| Discipline | Core Question It Answers | Primary Artifact | Typical Owner | What Fails Without It |
| DevOps | How do we ship software changes quickly and reliably? | CI/CD pipeline, infrastructure-as-code | Platform / SRE / engineering teams | Slow, error-prone, manual releases |
| MLOps | How do we get ML models into production and keep them accurate over time? | Model registry, feature store, retraining pipeline | Data science / ML engineering teams | Silent model decay, biased or stale predictions |
| AIOps | How do we detect, explain, and resolve operational issues faster than humans scanning dashboards? | Anomaly detection models, correlation engine, alert automation | IT operations / SRE teams, increasingly with data science support | Alert fatigue, missed incidents, slow root-cause analysis |
Where the Three Genuinely Overlap
This is the part most vendor content skips, because vendors sell one of these three categories and have an incentive to make it sound self-contained. In practice, the overlap is where most of the operational value and most of the coordination pain actually lives.
Where the Three Genuinely Overlap
| Overlap Zone | Who Meets Here | Why It Matters |
| Observability data | DevOps supplies logs, metrics, and traces; AIOps consumes them to find patterns; MLOps contributes model-performance metrics as another signal type. | If the three teams use different monitoring stacks, AIOps has an incomplete picture and will miss the root cause. |
| Pipeline automation | DevOps’ CI/CD and MLOps’ continuous training (CT) pipelines share the same underlying automation and versioning philosophy. | Teams that treat model pipelines as “just another deployment” often skip data validation steps that CI/CD was never designed to check. |
| Incident response | An AIOps platform flags an anomaly; the root cause could be infrastructure (DevOps’ job) or model drift (MLOps’ job). | Without a clear handoff process, incidents bounce between teams while the business impact keeps growing. |
| Toolchain consolidation | Platform engineering increasingly tries to unify DevOps, MLOps, and AIOps tooling under one internal developer platform. | Fragmented tools mean duplicated licensing costs and inconsistent data, which undermines the very automation these disciplines promise. |
The practical implication: if you’re evaluating an AIOps platform, ask how it ingests data from your existing DevOps observability stack and whether it can consume model-performance metrics from your MLOps pipeline. A tool that only watches infrastructure metrics will miss an entire category of production incidents the ones caused by a model quietly drifting, not a server going down.
A Decision Framework: Which One Do You Need First?
Most organizations don’t need all three at once, and building AIOps capability before DevOps maturity is one of the more common expensive mistakes. Use this rough sequencing logic as a starting point, then adjust for your specific risk profile.
1. Start with DevOps maturity if: releases are still manual, deployments regularly cause incidents, or your team can’t say with confidence what changed the last time something broke. There’s no AIOps or MLOps shortcut around a shaky release process.
2. Invest in MLOps if: you have one or more machine learning models in production (recommendation engines, fraud scoring, demand forecasting, diagnostic support tools) and no formal process for retraining, versioning, or monitoring them for drift.
3. Invest in AIOps if: your DevOps foundation is solid but alert volume has outgrown your team’s ability to triage manually; this is common once you’re running distributed microservices, multi-cloud infrastructure, or a large IoT/edge fleet.
4. Invest in all three, integrated, if: you’re running AI-powered products at meaningful scale, for example, an e-commerce recommendation engine, a healthcare triage model, or a fintech fraud system where a production incident could mean either infrastructure downtime or a model making bad decisions silently.
Common Mistakes Businesses Make With These Three Disciplines
Buying AIOps tooling before DevOps observability is solid
An AIOps platform is only as good as the data feeding it. If your logging and monitoring are inconsistent across services, the AI layer will correlate noise, not signal, and teams often abandon the tool within a year, blaming the technology rather than the missing foundation.
Treating MLOps as “DevOps for models”
The CI/CD mindset (build, test, deploy) doesn’t fully transfer to ML. Models depend on data that changes after deployment in ways code doesn’t. A model can pass every test on day one and become inaccurate three months later without any code change at all something a pure DevOps pipeline has no mechanism to catch.
Assuming AIOps replaces the SRE or ops team
AIOps tools are strong at detection and correlation, and increasingly capable at automated remediation for well-understood, repetitive issues. They are not yet a substitute for human judgment on novel incidents, business-context decisions, or anything with regulatory or customer-communication implications.
How These Disciplines Play Out Across Industries
Healthcare: a diagnostic-support model needs MLOps discipline (drift monitoring is a patient-safety issue, not just a data science concern) layered on top of DevOps practices that meet HIPAA-relevant change-control requirements. AIOps here often focuses on system uptime for clinical-facing applications, where downtime has direct care implications.
Retail and e-commerce: seasonal traffic spikes make AIOps valuable for catching infrastructure strain before it becomes a checkout outage, while MLOps keeps recommendation and pricing models accurate as buying behavior shifts week to week.
FinTech: fraud-detection and credit-risk models require tight MLOps governance because a drifting model can mean real financial exposure or compliance risk, while DevOps change-control and audit trails are often mandated by regulators rather than optional best practice.
Manufacturing and logistics: predictive-maintenance models depend on MLOps to stay accurate as equipment ages and sensor data shifts, while AIOps is typically applied to the IT and OT infrastructure monitoring the plant floor or fleet in real time.
SaaS and startups: early-stage companies usually get more return from tightening DevOps practices than from adopting either MLOps or AIOps; those become relevant once the product has models in production and enough infrastructure complexity to generate real alert fatigue.
Building a Roadmap That Connects All Three
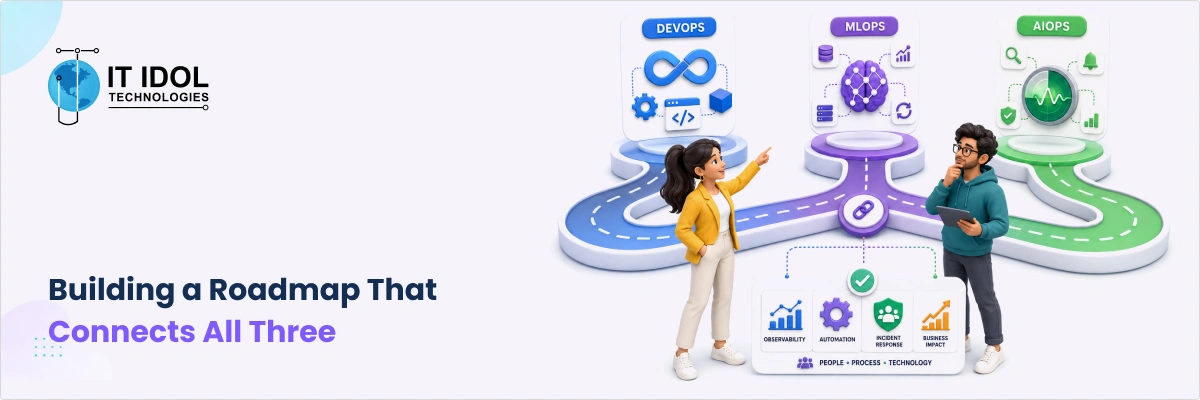
Rather than treating DevOps, MLOps, and AIOps as separate initiatives with separate budgets, the organizations that get the most value tend to follow a similar sequence:
- Audit what you actually have today: pipelines, monitoring tools, and any models already in production, including ones the business may not realize are quietly running.
- Fix observability gaps first. A unified, consistent logging and metrics approach is the prerequisite for both MLOps monitoring and AIOps correlation; skipping this step undermines everything built on top of it.
- Formalize MLOps only where models exist. Don’t build model governance infrastructure speculatively; build it where there’s a model in production today or firmly on the roadmap.
- Introduce AIOps incrementally, starting with the highest-noise, lowest-context alerts the ones your team already resents triaging manually rather than trying to automate everything at once.
- Define incident-response ownership across all three teams before you need it, so that when AIOps flags an anomaly, there’s a clear path to whichever team infrastructure or model actually owns the fix.
Key Takeaways
• DevOps, MLOps, and AIOps solve different core problems: shipping code, maintaining models, and monitoring operations, respectively.
• They overlap most in observability data, pipeline automation philosophy, and incident response, not in day-to-day ownership.
• Sequencing matters: DevOps maturity is usually the prerequisite for getting real value from either MLOps or AIOps.
• Buying AIOps or MLOps tooling before the underlying DevOps foundation is solid is one of the most common and costly mistakes.
• The right sequence and depth of investment depends heavily on industry risk profile; a fintech fraud model and a retail recommendation engine don’t need the same level of MLOps rigor.
Where to Go From Here
Deciding where DevOps, MLOps, and AIOps overlap in your own environment isn’t really a definitions exercise; it’s an audit of what you’re already running, what’s monitored, and where the gaps sit between teams. That’s usually where an outside perspective helps most: not to sell a new platform, but to map what you have against what your risk profile actually requires.
IT IDOL Technologies works with engineering and IT leadership teams across custom software development, AI and machine learning engineering, and product engineering to build the DevOps, MLOps, and AIOps foundations that fit where a business actually is today, not a generic maturity model. If you’re trying to figure out which of these three disciplines deserves your next quarter’s budget, that conversation is a reasonable place to start.